Live Demo · Medical Clinic AI Receptionist
Talk to a
Medical AI Phone Agent
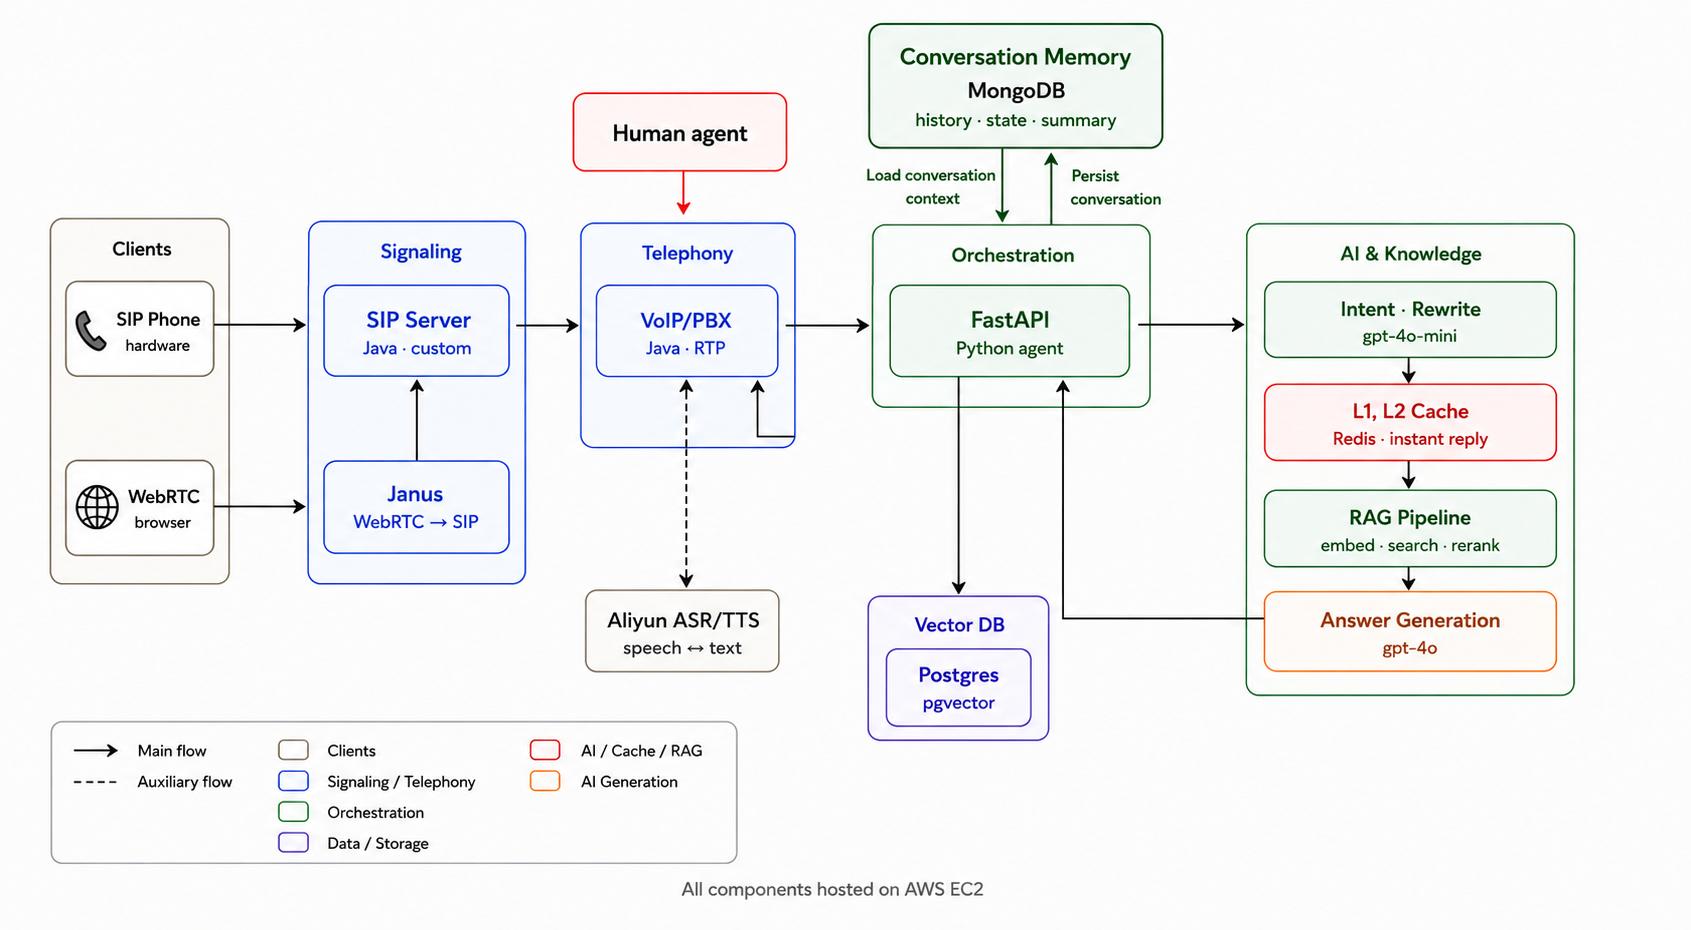
A live call to a production AI voice agent for a family clinic. I designed and built every layer myself, from SIP signalling and the media engine to the RAG pipeline and intent classifier. Both call paths reach the same agent, with a end-to-end response.
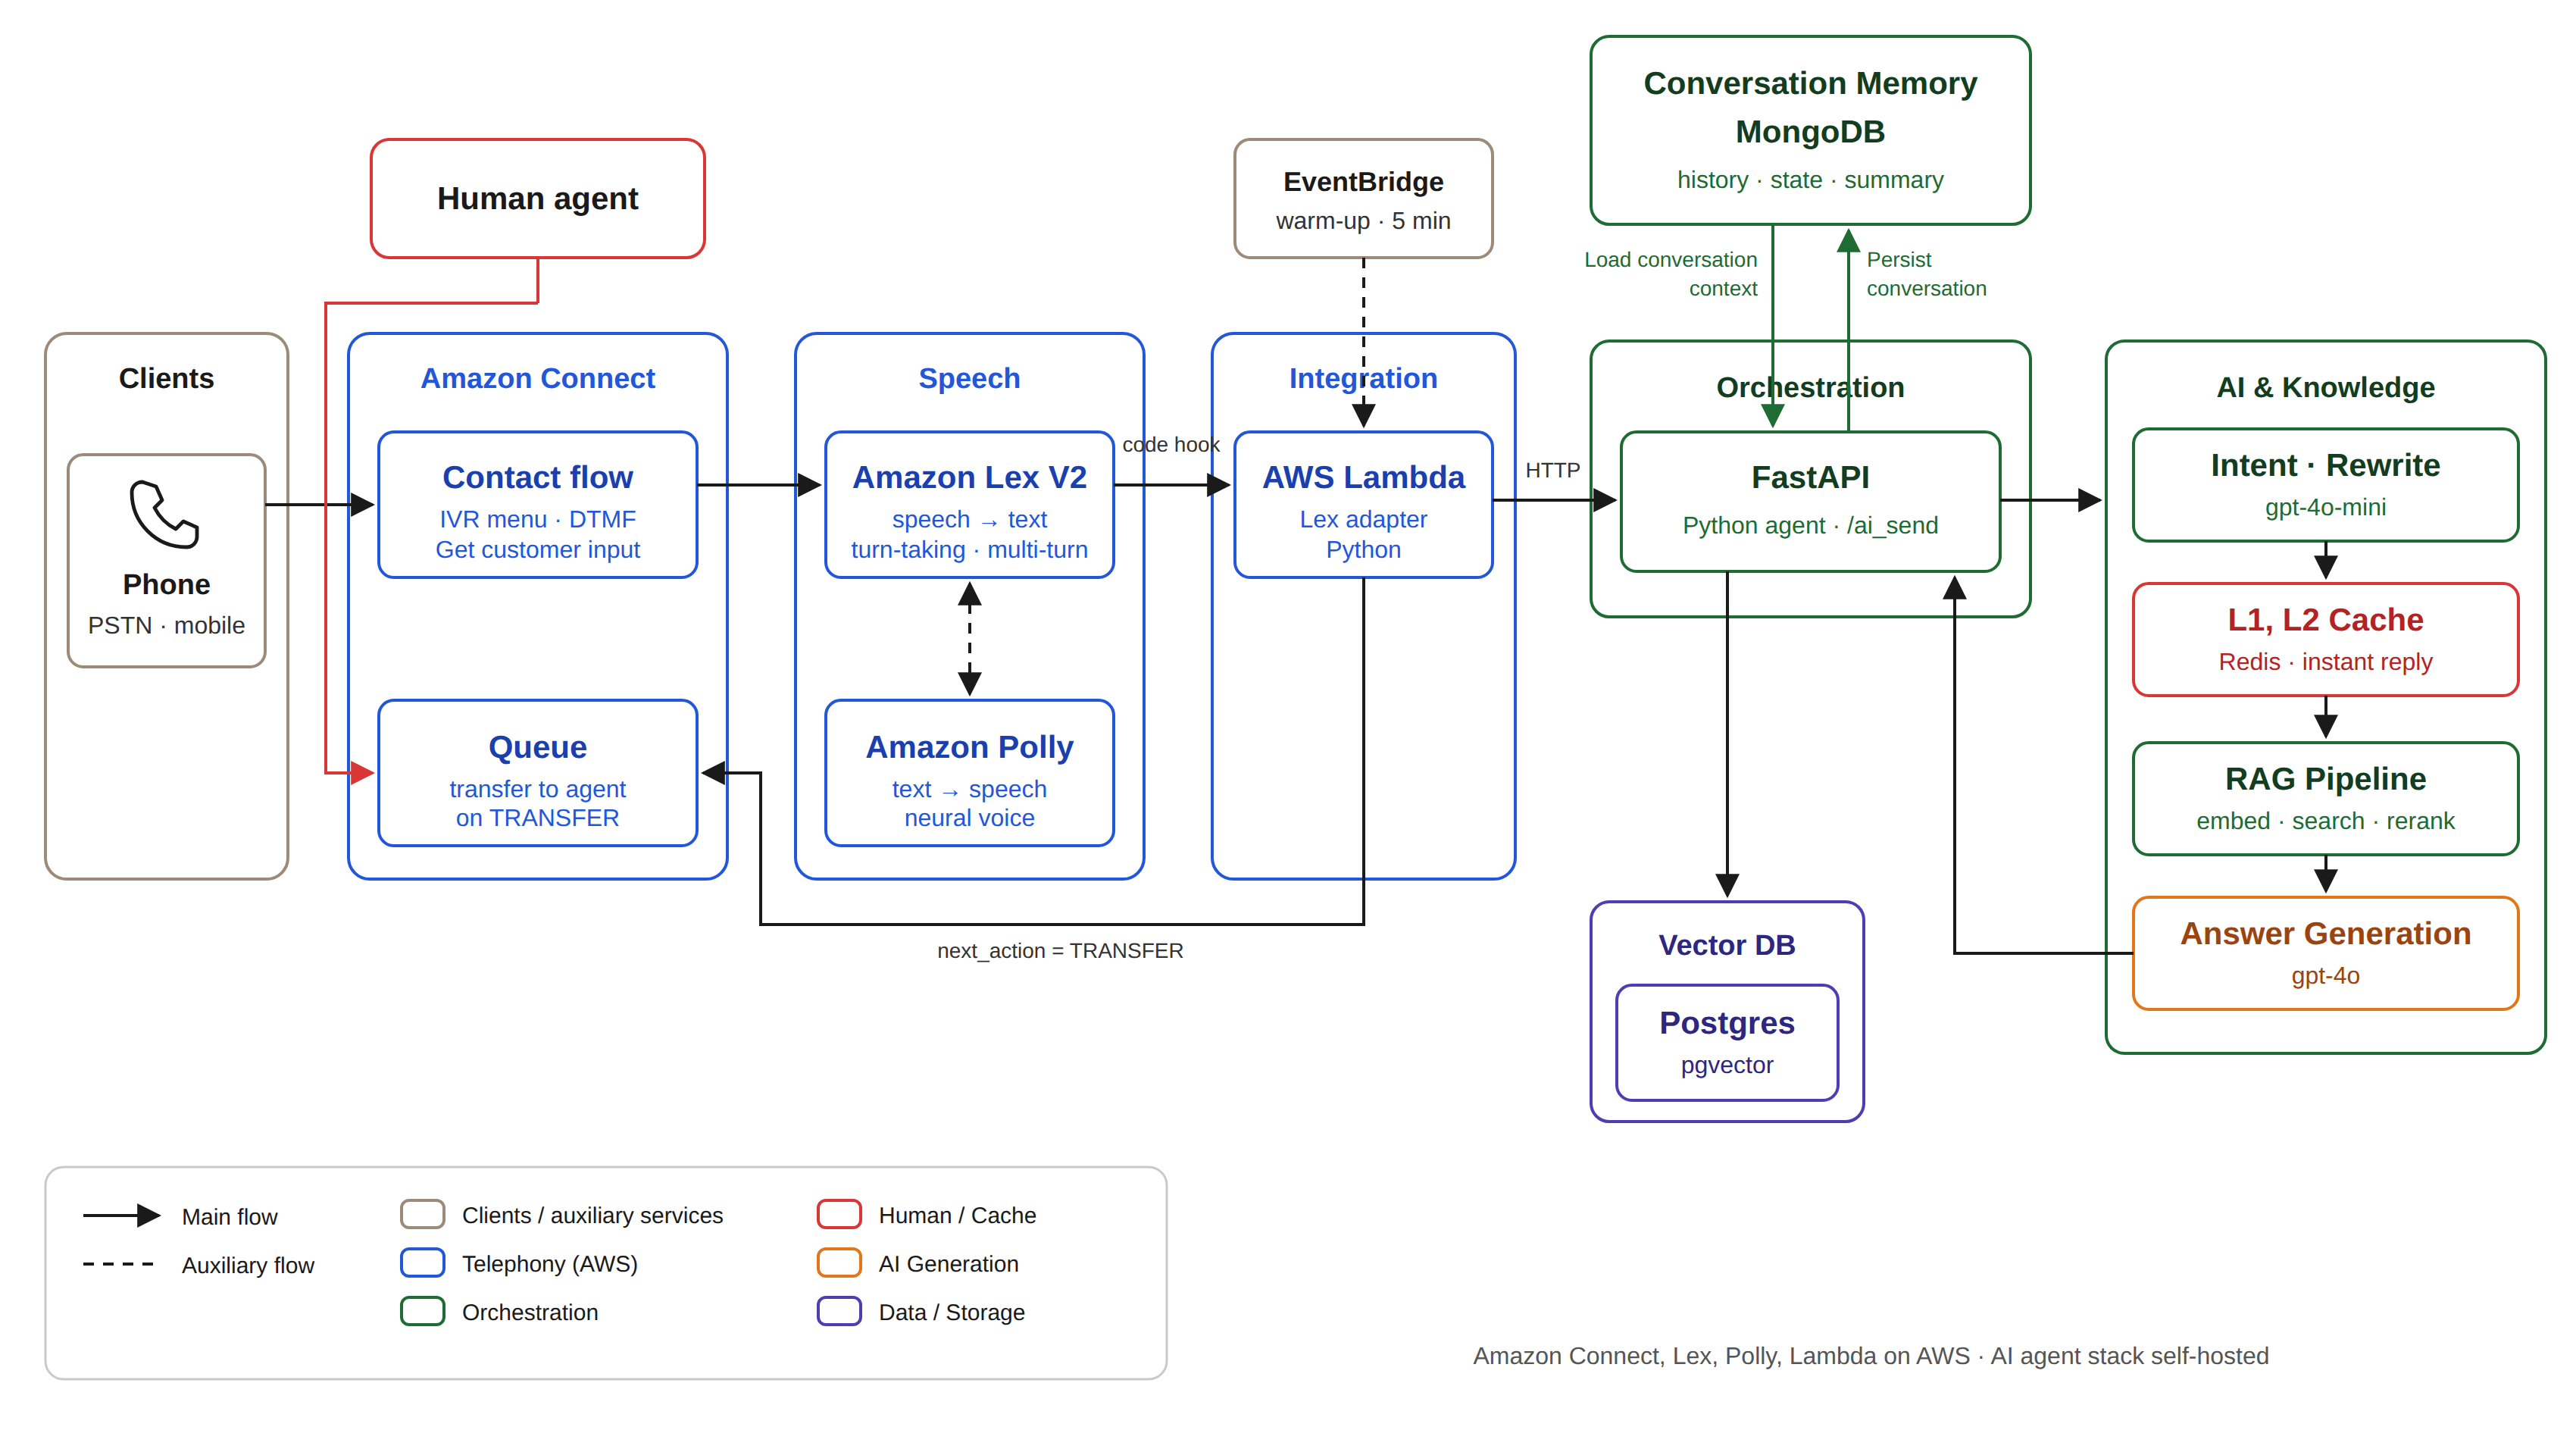
- Method 1Call from your phoneKey 1: Amazon Connect IVR → Amazon Lex V2 → AWS Lambda → my AI agent, spoken by Amazon Polly.
Key 2: a self-service booking line on an Amazon Lex V2 bot that I designed, using Lex NLU and slot filling, with Python Lambda code hook behind it. It verifies the caller once per call, then books, checks or cancels appointments in DynamoDB, with a conditional write so each patient holds only one booking. - Method 2Call from your browserYour browser → Janus WebRTC → my own Java SIP server and VoIP media engine → Aliyun ASR/TTS → AI agent. The SIP stack grew out of the PBX I built and sold to over 500 businesses. The agent runs two-stage RAG (BGE embeddings, pgvector, reranker), a 5-class intent classifier and a two-tier Redis cache.
Choose how to call
Call from any phone; standard call rates apply. Your phone → Amazon Connect IVR → Amazon Lex V2 → AWS Lambda, spoken by Amazon Polly. Key 1 goes on to my AI agent; key 2 stays in a Lex bot and stores bookings in DynamoDB.
-
1Talk to the AI assistantLex V2 + Harvey's Python agent (RAG + LLM)
- Working hours"What are your clinic hours?" · "Are you open on weekends?"
- Location"Where is the clinic?" · "Is there parking nearby?"
- How to book"How do I book an appointment?" · "Do you accept walk-ins?"
- Cancellation policy"What if I can't make it?" · "How much is the cancellation fee?"
- More topicsSick notes, refills, referrals, new patients, and anything else in the knowledge base
-
2Manage appointmentsLex V2 NLU + slot filling + AWS Lambda
- Book an appointment
- Check my appointment
- Cancel my appointment
Identity check firstTest with these details:Health number 1234567890
Date of birth March 5, 1989Lambda + DynamoDB, one booking per patient -
3How this system was built0Talk to a person#Repeat the menu
Ask for a person at any time, or press 0 to be transferred to Harvey.
More intents to try:
Try asking (QUERY):
Chitchat:
Please ask me a question about the clinic knowledge base ▾
About This System
Intelligent Voice Agent for Medical Clinics
A production-grade AI phone assistant built from the ground up — custom Java SIP signalling server, VoIP media engine, Aliyun ASR/TTS, local RAG pipeline with BGE embeddings and pgvector, real-time 5-class intent classification, and sub-2s end-to-end latency. The same agent also answers calls through Amazon Connect, bridged by Amazon Lex V2 and AWS Lambda.
Key Technical Highlights
What Makes It Work
Changelog
Update History
October 2026
Self-service Booking Line (key 2)Built in 1 day
Added an Amazon Lex V2 bot for booking, checking and cancelling family-doctor appointments. Lex handles intent recognition and slot filling; a Python Lambda code hook reads back and verifies the caller's health number and date of birth once per call, then reads and writes DynamoDB. A conditional write enforces one appointment per patient, health numbers are masked in logs, and Lambda's IAM role can reach only that one table.
October 2026
Amazon Connect Phone Line (key 1)Built in 2 days
The agent now also answers real phone calls at +1 236-466-1681. The IVR and the bridge to my agent were built in two days. Amazon Connect runs the IVR menu, Lex V2 transcribes speech, and a Lambda adapter forwards each turn to the same RAG and intent backend. Includes silence handling, timeout retry, scheduled warm-up, and live-agent transfer.
June 5, 2026
L1 / L2 Redis Semantic Cache
Two-tier Redis cache intercepts repeat and paraphrased queries before RAG — exact match under 5ms, semantic match under 300ms. Includes FAQ warmup, fallback detection, and cache export tool.
Copyright & Attribution